Deep-tech engineering · artms.io
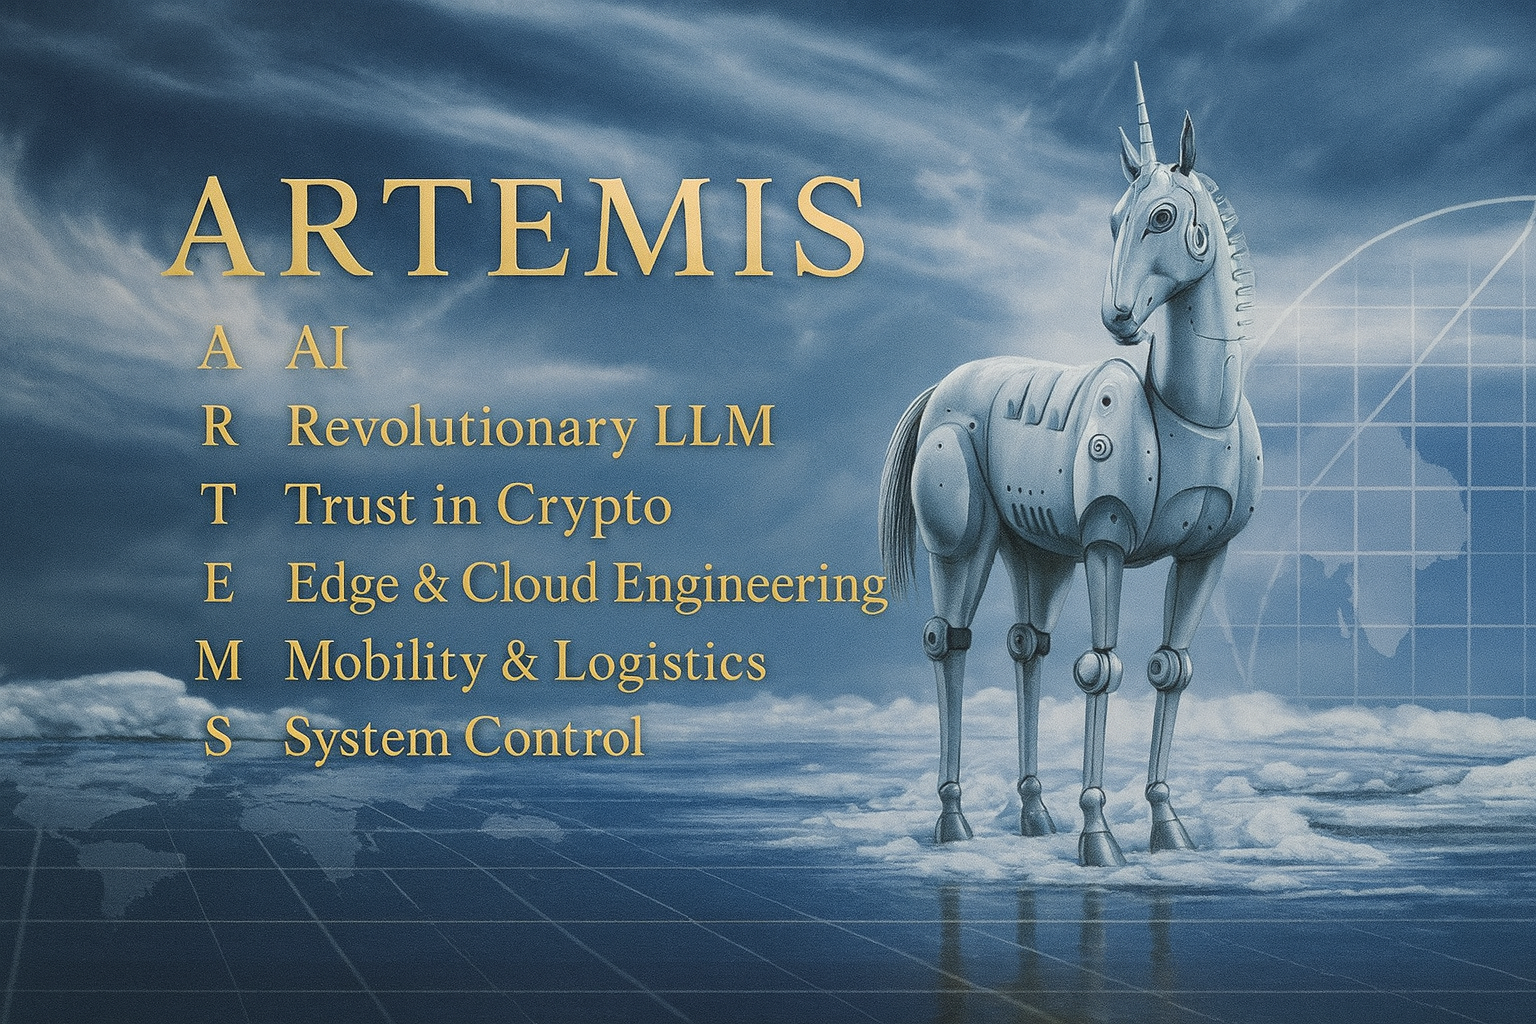
ARTEMIS
An engineering company building AI, next-generation language models, trusted crypto infrastructure, edge & cloud platforms, mobility and logistics systems, and mission-critical system control.
What ARTEMIS stands for
Six disciplines, one engineering practice. Each letter is a capability we build, run and stand behind — and together they cover the full path from raw data to a system operating in the field.
- A
AI
Applied artificial intelligence that turns data into decisions.
See AI in detail - R
Revolutionary LLM
Next-generation language models built for precision, safety and real-world deployment.
See Revolutionary LLM in detail - T
Trust in Crypto
Secure, auditable blockchain and digital-asset infrastructure you can rely on.
See Trust in Crypto in detail - E
Edge & Cloud Engineering
Distributed systems that run where they're needed — from the data center to the device.
See Edge & Cloud Engineering in detail - M
Mobility & Logistics
Intelligent platforms for moving people, goods and data efficiently.
See Mobility & Logistics in detail - S
System Control
Robust control and automation for mission-critical operations.
See System Control in detail
Open a letter, see the work behind it
Each pillar below expands into what we actually build, the deliverables that leave our hands, and the shapes of engagement teams usually start with.
In applied AI the model is rarely the hard part. We start from the decision — what is predicted, who acts on it, and what it costs when the answer is wrong — then build backwards into the data. Models are evaluated against operational reality rather than a leaderboard, shipped behind interfaces your teams already use, and watched in production so drift is caught before anyone downstream feels it.
Typical engagements
- Discovery sprint
- Proof of concept to production
- Embedded AI team
- Model audit and remediation
What we deliver
Data and feature pipelines
Ingestion, labelling workflows and feature definitions that keep training inputs and production inputs identical.
Evaluated, production-ready models
A baseline, candidate models and an evaluation harness scored on operational cost — not accuracy alone.
Decision interfaces
APIs, dashboards and in-workflow surfaces that place a prediction exactly where the decision is made.
Monitoring and retraining
Drift detection, shadow deployments and scheduled retraining with a documented path back to a known-good version.
A language model earns its place when it is grounded, constrained and measurable. We design retrieval and tool-use architectures over your documents, tickets and telemetry, tune against evaluation sets built from real tasks, and put guardrails wherever a wrong answer would be expensive. Deployment runs from managed APIs through to models serving entirely inside your own network.
Typical engagements
- Assistant build
- Evaluation and guardrail review
- Private model deployment
- Team enablement
What we deliver
Retrieval-grounded assistants
Retrieval architecture over your corpus, with tool use, permissions and citations back to the source document.
Evaluation harness
Task-level test sets, regression runs and scoring so that changing a prompt or a model is a measured change.
Guardrails and safety layer
Input and output filtering, tool permissioning, sensitive-data handling and human-in-the-loop escalation.
Fine-tuning and private inference
Adapter training and self-hosted serving for data and workloads that cannot leave your estate.
Digital-asset systems are judged on what happens on their worst day. We design custody, settlement and on-chain integrations around an explicit threat model: where key material lives, which signing paths exist, who has to approve what, and what evidence survives the incident. Contracts are specified before they are written and independently reviewed before they ever hold value.
Typical engagements
- Security architecture review
- Contract audit and hardening
- Custody platform build
- Monitoring retainer
What we deliver
Threat model and key architecture
Custody design, hardware or multi-party signing paths, approval quorums and a rehearsed recovery procedure.
Smart contract design and review
Specification, implementation, property-based test suites and independent review ahead of deployment.
Settlement and reconciliation
On-chain and off-chain reconciliation, ledgering and exception handling built for the people who close the books.
Audit and control evidence
Tamper-evident logging, reporting and controls documentation your auditors and regulators can actually use.
The same workload behaves differently in a data centre, a regional cloud and a box bolted to a machine on a factory floor. We place compute deliberately — latency, bandwidth and failure domain decide where code runs — and then make the whole estate deployable from one pipeline, with one honest view of its health whether a node is in a region or in a truck.
Typical engagements
- Platform build
- Cloud and edge migration
- Cost and performance review
- Managed platform operation
What we deliver
Reference architecture
Cloud, regional and on-device tiers with explicit data flows, latency budgets and failure boundaries.
Infrastructure as code and delivery
Reproducible environments, progressive rollout and rollback that treat a device fleet like any other target.
Edge runtime and fleet management
Constrained-hardware runtimes, over-the-air updates and offline-first sync that survives a lost link.
Observability and SLOs
Metrics, traces, logs and service objectives that cover the edge as thoroughly as the core.
Moving people, goods and data is an optimisation problem wrapped in an operational one. We build the telemetry backbone first so the network has a truthful real-time state, then the planning and routing on top of it, then the tooling dispatchers and drivers hold in their hands — because a plan nobody on the ground can execute is not a plan.
Typical engagements
- Network modelling study
- Routing platform build
- Fleet telemetry rollout
- Continuous optimisation partnership
What we deliver
Telemetry and tracking backbone
Vehicle, asset and sensor ingestion producing one real-time state of the network across every partner system.
Routing and scheduling engines
Constraint-aware planning for routes, loads, shifts and depots, with what-if simulation before anything moves.
Dispatch and driver tooling
Operations consoles, exception queues and mobile apps built to keep working on poor connectivity.
Integration layer
Transport, warehouse, ERP and partner APIs joined into a single operational picture rather than six tabs.
Control systems are where software meets consequences. We build the supervisory, automation and safety layers for operations that cannot simply be turned off and on again: defined operating states, deterministic transitions, tested failure paths, and an operator who is never left guessing what the system is doing or why it did it.
Typical engagements
- Controls design review
- Automation build and commissioning
- Legacy system modernisation
- Round-the-clock operational support
What we deliver
Control architecture and state model
Operating states, interlocks and transitions specified and reviewed before a line of control logic is written.
Supervisory and plant integration
Controller, sensor and historian integration over segmented, monitored networks with least-privilege access.
Operator interfaces and alarm design
Interfaces built around alarm rationalisation, situational awareness and unambiguous escalation paths.
Simulation, testing and commissioning
Hardware-in-the-loop and digital-twin testing, plus factory and site acceptance support through go-live.
A disciplined path from problem to production
- 01
Understand
Deep discovery of your domain.
We start inside your operation — the data, the constraints, the regulation, the people. Nothing is engineered before the problem is understood on its own terms.
- 02
Engineer
Secure, scalable systems built by senior engineers.
Architecture first, then code. Threat modelling, review and testing are part of delivery rather than something bolted on at the end.
- 03
Operate
Monitoring, control and continuous improvement.
Systems are measured in production. We instrument, observe, tune and keep improving long after the first release ships.
Engineering for the real world
ARTEMIS is a technology company at the intersection of artificial intelligence, secure infrastructure and real-world systems. We build the software that decides, protects and controls — models that reason over live data, platforms that carry value safely, and control layers that keep physical operations running when failure is not an option.
Our work spans the full stack of a modern system: from the edge device and the network, through the cloud and the model, to the operator's screen. We take the whole responsibility — design, delivery and the years of operation that follow.
Why ARTEMIS
Senior engineering team
Systems designed and delivered by engineers who have run them in production.
Security-first
Threat modelling, auditability and least privilege built in from the first commit.
Built for scale
Architectures that hold their shape from first pilot to global deployment.
Long-term partnership
We stay with the system — operating, hardening and evolving it over years.
Systems that hold their shape at global scale.
From a single edge device to a worldwide fleet — one architecture, measured and controlled end to end.
- Six
- Engineering pillars
- End to end
- Edge to cloud delivery
Let's talk about the system you need to build
Tell us about the problem, the constraints and the timeline. A senior engineer reads every message and replies personally.
Emailhello@artms.io